The Key to Success in Artificial Intelligence, Deep Learning and Image Processing
The importance of the dataset in AI projects, and the foundations of success in deep learning and image processing applications.
The Key to Success in Artificial Intelligence, Deep Learning and Image Processing: Principles of Excellent Data Preparation
The age of Artificial Intelligence (AI) is a vast technological wave transforming every area of our lives and opening the way to smarter, faster and more efficient systems. From instant translation on our smartphones to the complex road decisions of autonomous vehicles, and even the detection of diseased cells at microscopic level, AI applications are developing and maturing at incredible speed. Deep Learning in particular began to accelerate as data grew more plentiful. One of the most popular and impressive fields in which this powerful set of algorithms is applied is Image Processing. But there is a critical secret to unlocking the full potential of these technologies: rigorously applied principles of data preparation.
✨ The Depths of Artificial Intelligence and Deep Learning
In its broadest definition, Artificial Intelligence is the branch of science that enables machines to learn, reason, solve problems and ultimately make autonomous decisions much as a human would. Beneath AI sits Machine Learning, which lets machines learn patterns and relationships from large volumes of data.
Deep Learning is a subset of Machine Learning that uses Deep Neural Networks inspired by the biological neural networks of the human brain. These networks take an input (a photograph, say), process the information through hidden layers arranged one after another, and produce an output (the label of the object in the photograph, for instance). Unlike traditional methods, this "deep" structure gives the ability to learn complex and abstract patterns in data automatically, by building a deep hierarchy across the layers.
💡 What sets Deep Learning apart: in traditional Machine Learning methods, an expert has to determine and extract the meaningful features of the data (feature engineering) by hand, whereas Deep Learning models — architectures such as Convolutional Neural Networks (CNNs) in particular — can learn these features by themselves, directly from raw data. This capability has made Deep Learning indispensable for big data and complex tasks.
🖼️ Pushing Past the Limits in Image Processing with Deep Learning
Image Processing is the process of analysing and modifying digital images and extracting high-level meaningful information from them. Deep Learning created a revolution by separating Image Processing from the older rule-based systems. Today, Deep Learning models based on Convolutional Neural Networks (CNNs) can reach levels of accuracy exceeding human perception and analysis in tasks such as:
- Object recognition and detection: determining what the different objects in an image are, where they are and which class they belong to (detecting vehicles, pedestrians and cyclists in traffic in real time, for example).
- Image classification: determining which category an image as a whole belongs to (classifying whether a medical MRI scan contains a tumour, for instance).
- Semantic segmentation: labelling every pixel in an image according to the object class it belongs to and determining precise boundaries (separating water, forest and built-up areas at pixel level in geographic imagery, for example).
One factor alone makes this superior performance possible: large, high-quality and well-prepared datasets.
🔑 The Golden Rule of Success: Principles of Data Preparation
Deep Learning models are only as good as the quality and variety of the dataset they are trained on. If a model is trained on rubbish, its output will be rubbish too — the "garbage in, garbage out" principle. Data preparation is the process of taking raw, disordered data and converting it into a form the model can learn from effectively and generalise from to real-world problems. This process usually accounts for 60 to 80 per cent of an AI project and is the most critical stage in its success.
Here are the core data preparation principles to follow for excellence in image processing projects:
Data Collection, Variety and Balance (The Foundation)
Building a Deep Learning model on solid ground starts with data collection:
- Relevance and coverage: the data collected has to represent the problem to be solved across every possible real-world scenario. Training a security camera model using only images in sunny daylight will cause it to fail completely at night or in fog. The dataset should cover every lighting, weather and angle condition.
- Resolving class imbalance: large differences in the number of examples between classes in a dataset (class imbalance) cause the model to weight the more numerous class during training and ignore classes with fewer examples, which may be the critical ones (medical anomalies, for instance). This should be corrected through techniques such as undersampling, oversampling or synthetic data generation (SMOTE and similar).
Data Preprocessing and Normalisation (The Clean-up)
Getting raw images ready to be processed improves the efficiency of learning:
- Cleaning noise and distortion: low-resolution, blurred or overexposed images, or those containing sensor errors, blunt a model's ability to discriminate. This data should be cleaned or corrected with enhancement algorithms.
- Resizing and standardisation: many models require a fixed input size (224 × 224 pixels, for instance). Every image should be scaled to that size, and pixel values should also be put through normalisation (usually bringing them between 0 and 1, or between −1 and 1) and standardisation (using the mean and standard deviation). This makes the model's training more stable and shortens the time to convergence.
Labelling and Annotation Quality (The Truth)
Data labelling is where the model learns the "truth". The smallest error here can ruin the whole model:
- Precision and consistency: the labelling of objects and categories in an image must be precise, accurate and consistent across the whole dataset. In image processing this is done with bounding boxes, polygon drawing or pixel-level segmentation masks. If one annotator draws an object's boundary 5 pixels inside the edge and another 5 pixels outside it, the model becomes confused.
- Labelling standards: creating a standardised, clear labelling guide shared between annotators is essential to keeping labelling quality high. Quality control mechanisms should ensure labelling errors are identified and corrected quickly.
Data Augmentation (The Growth Hack)
The most effective way to get maximum value from a small dataset and improve a model's ability to generalise is data augmentation — applying random transformations to existing images that do not change their semantic content:
- Geometric transformations: rotating the image by random angles, flipping it horizontally or vertically, shifting it, and random cropping.
- Photometric transformations: making random changes to brightness, contrast, colour saturation and sharpness.
These techniques make the model more robust against small variations it did not see in training but may meet in the real world, and they prevent overfitting.
🚀 Sector Applications and a Professional Approach
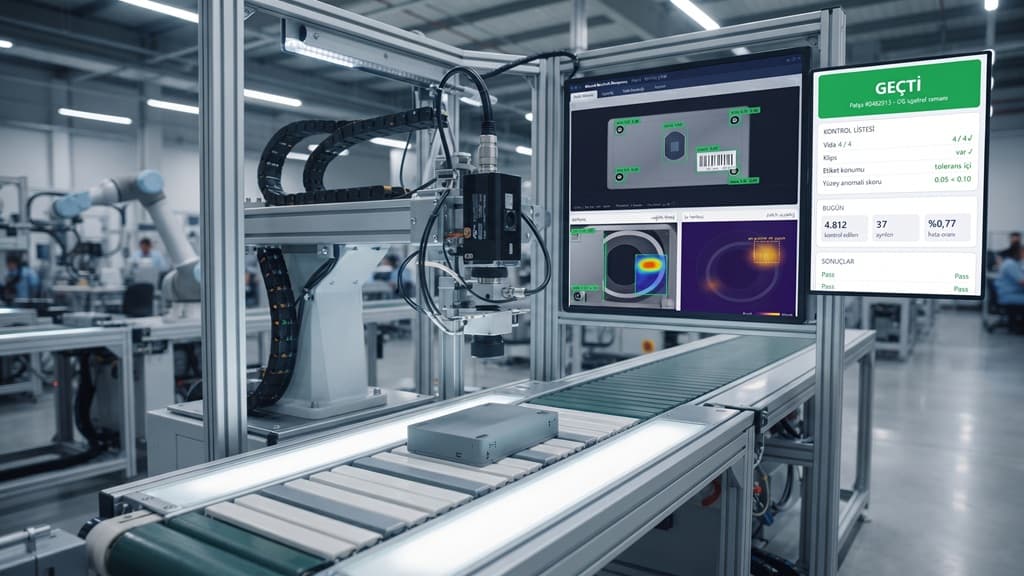
Artificial intelligence, deep learning and image processing technologies are opening new doors to efficiency everywhere — from industrial quality control (defect detection) to fast, accurate diagnosis in healthcare (radiology analysis), and from retail (shelf analysis) to security (facial recognition). In these complex, high-stakes projects, managing data preparation rigorously and professionally in particular makes a project not only successful but ethical and trustworthy too.
If you are looking for a dependable, experienced and expert partner in this critical field, the advanced technology solutions and expertise Arca Yazılım offers are the right place to put your projects on solid ground and take them a step further. With quality software development methodologies, customised Deep Learning model architectures and data preparation processes held to high standards, Arca Yazılım will be your greatest support on your digital transformation journey.
To make sure your dataset forms the right foundation for artificial intelligence, to get detailed information about your projects and to make use of technical consultancy services, you can contact the Arca Yazılım team at info@arcateknoloji.com. To learn more about all the services Arca Yazılım offers and its impressive references, please visit the official website at www.arcayazilim.com.